OpenAI's Decisions API Is Now Live for Everyone: 10x Faster AI Calls in 100 Milliseconds
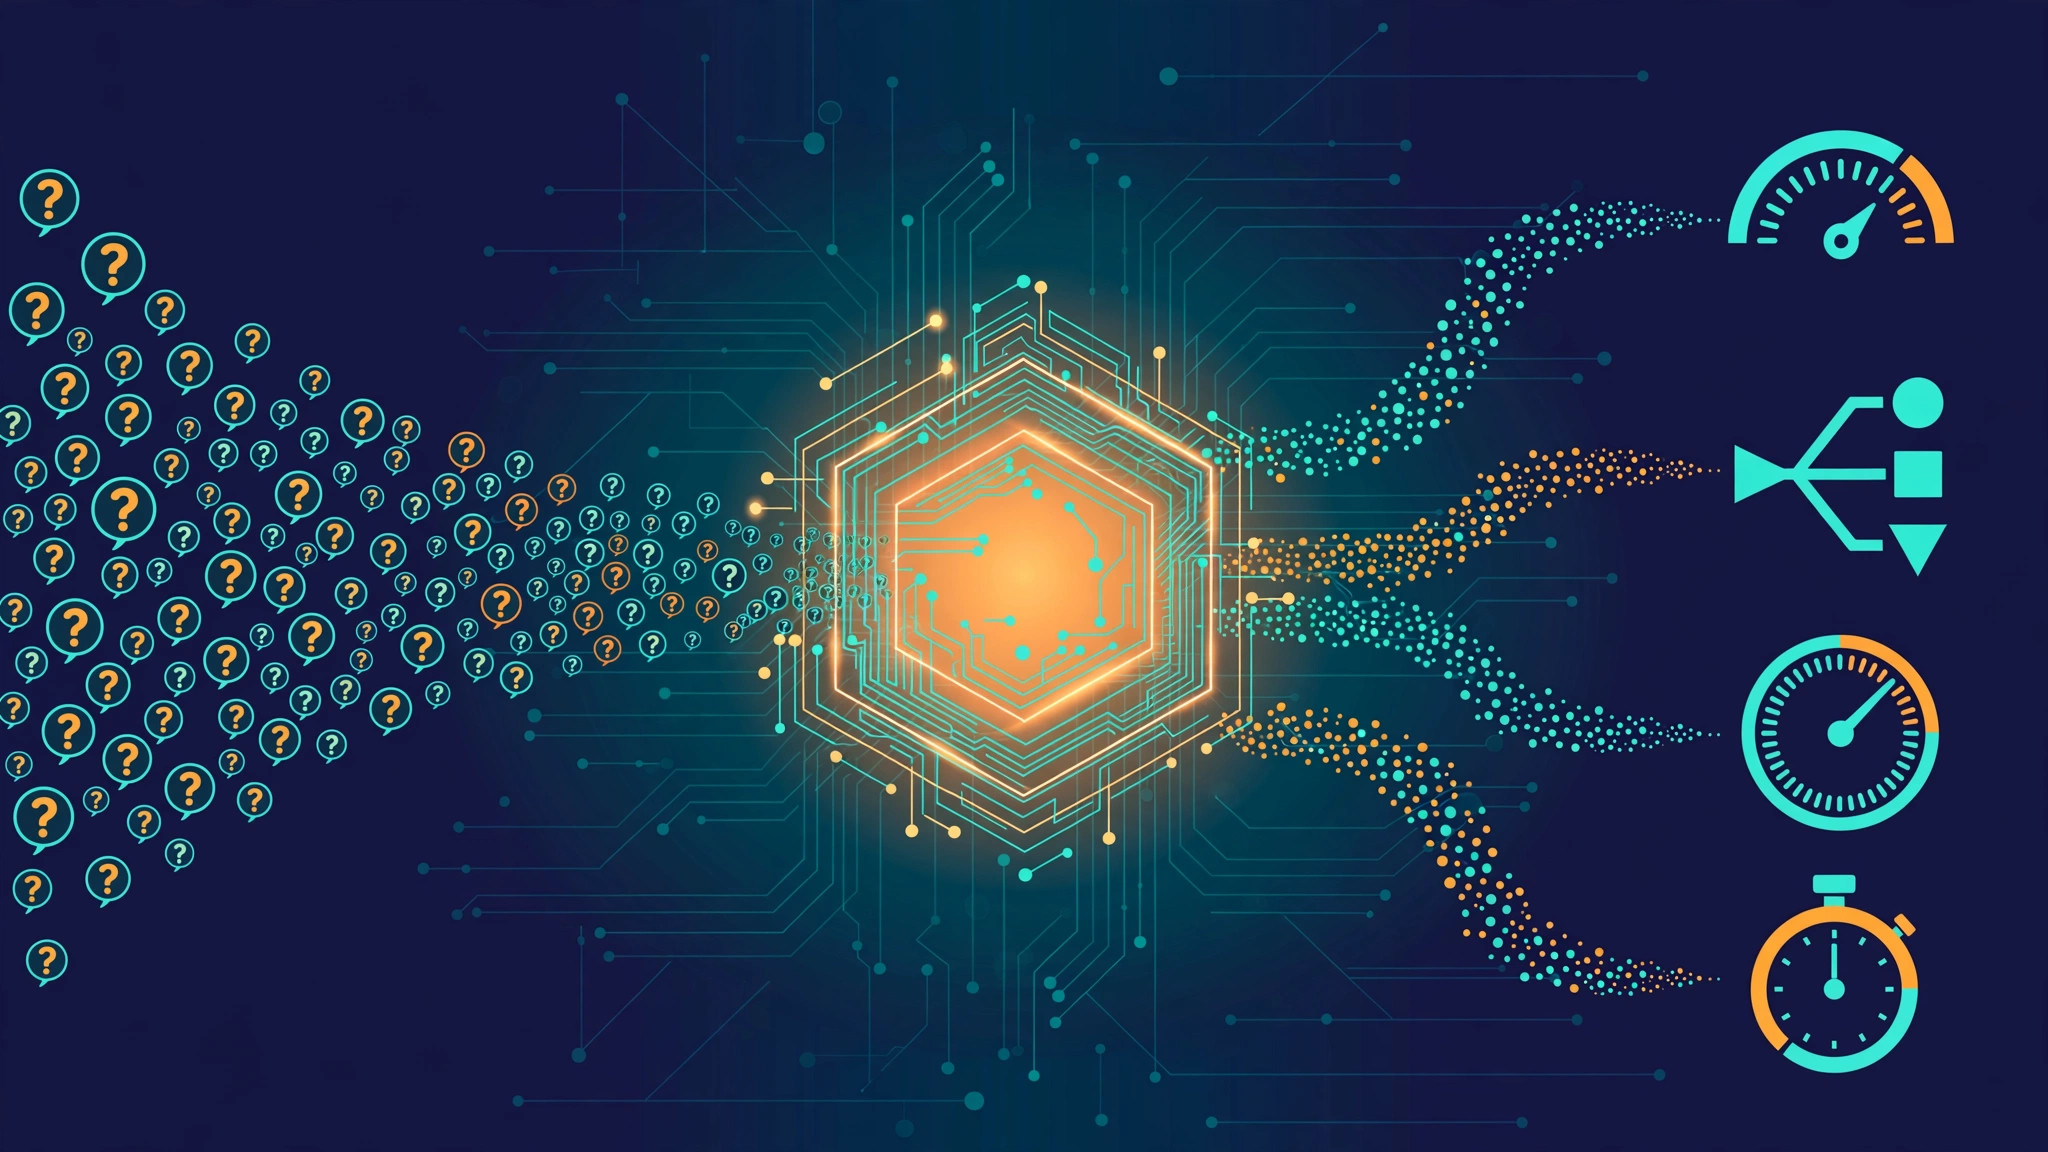
Most AI API calls end the same way: the model writes a paragraph, and your code digs through the paragraph to find the one word it actually needed. OpenAI just shipped an API that skips the paragraph entirely.
On October 22, 2026, OpenAI made the Decisions API generally available to every customer. It is a dedicated endpoint — POST /v1/decisions — that does not generate text at all. Instead, it returns typed answers: a probability that something is true, a choice picked from a list you supply, or a score against a rubric you define. According to OpenAI, it answers up to 10x faster than running the same model through the Responses API, with response times that OpenAI API product lead Nikunj Handa says fell from 1–3 seconds down to 100–180 milliseconds.
The pricing is as aggressive as the latency. Decisions costs $0.10 per million input tokens, drops to $0.01 per million for cached input, and charges nothing for output — because there is no generated output to charge for. The API first appeared at OpenAI's DevDay on September 29, 2026, entered public beta on October 6, and reached general availability just over three weeks later, which tells you something about how urgently OpenAI wanted this category covered.
That category — fast, cheap "decision models" that classify instead of chat — was created by a startup, TypeSafe, whose Jev model turned it into a company valued at around $7.6 billion. OpenAI is now contesting it directly, on Jev's home turf, with the full weight of its ecosystem behind it. This guide covers what the Decisions API actually does, how the three question types work with real examples, what it costs when you run the arithmetic honestly, where it beats the Responses API and Structured Outputs, where Jev still wins, and who should adopt it now.
Decisions API at a glance
| Item | Detail |
|---|---|
| Status | Generally available as of October 22, 2026 (public beta began October 6, 2026; first announced at DevDay, September 29, 2026) |
| Endpoint | POST /v1/decisions |
| Model | gpt-6-luna — the only supported model |
| Question types | Predicate, choice, score |
| Questions per request | Up to 400 (raised from the beta limit) |
| Inputs | Text, images (inline base64 or public URLs), JSON / structured input |
| Speed | Up to 10x faster than the Responses API, per OpenAI; 100–180ms responses cited by OpenAI's Nikunj Handa |
| Price | $0.10 per 1M input tokens; $0.01 per 1M cached input tokens; no output-token charge |
| New at GA | Native GPT-Live (voice) integration, prompt caching |
| Compliance | Zero Data Retention and HIPAA eligibility for qualifying customers; regional processing in the US and Europe |
| Named launch customers | Box, Datadog, Ramp, Sierra, Speak |
| Official guide | OpenAI Decisions API guide |
Why OpenAI built an API that refuses to write
To understand the Decisions API, it helps to look at how much production AI work is not really "generation" at all. A support platform does not need an essay about a ticket; it needs to know which queue the ticket belongs to. A payments app does not need a paragraph about a transaction; it needs a category. A moderation pipeline does not need commentary on a photo; it needs to know whether the photo breaks a rule, and how confident the model is.
Until now, developers have mostly served those needs with general chat models — the same class of system we compare in our ChatGPT vs Claude vs Gemini breakdown — and then parsed the prose back into a label. That works, but it is slow, it costs output tokens on every call, and the answer arrives wrapped in text your code has to interpret, validate and sometimes repair.
The Decisions API inverts the contract. You declare the shape of the answer before the call: the question, and the set of answers that are allowed. The model evaluates the input against that contract and returns numbers and values your code can branch on directly. There is no JSON to rescue, no free-text answer to misread, and no output tokens on the bill.
It is also a deliberately narrow product. OpenAI's own guidance is blunt: use Decisions when you need a probability, a choice or a score; use Structured Outputs on the Responses API when you need the model to produce an object in your own JSON schema, extract fields, or write an explanation. Decisions is a judgment layer, not a writing layer — and OpenAI is pricing and engineering it like one.
The timing matters too. GPT-6 Luna, the model behind the endpoint, launched on September 22, 2026 alongside GPT-6 Sol, sitting below the flagship GPT-6 Astra (the model whose naming saga we covered in our GPT-6.1 Astra story). Luna was always the high-volume, low-price tier of the family. The Decisions API is what happens when OpenAI takes that tier and strips away everything except the verdict.
The three question types, explained with examples
Every Decisions request asks one or more questions, and each question is one of three types. Understanding these three types is understanding the whole product.
1. Predicate: "How likely is this true?"
A predicate question checks whether a condition holds and returns a probability from 0 to 1 that it does.
OpenAI's own example is a product photo: does this item show visible damage — a crack, a tear, a dent? You send the image (inline base64 or a public URL) with the question, and the API returns something like a probability of 0.92. Your code then applies a policy: above your threshold, flag it; below it, let it pass.
The probability is the point. A bare yes/no forces you to accept the model's judgment at face value. A probability lets you build a gradient — auto-approve the clear cases, route the borderline ones to a human, and reserve judgment where the cost of being wrong is high. OpenAI is explicit that the threshold is yours to set, calibrated on your own labelled examples, and weighted by what a false positive costs you versus what a false negative costs you. Those two costs are rarely equal, and the API is designed around that fact.
2. Choice: "Pick one of these"
A choice question selects one value from a list you supply, and returns the winning value, a probability for every option, and an overall confidence figure.
The canonical example is support routing. A customer writes "I was charged twice for my order." You offer the API four choices — billing, technical, shipping, other — each with a short description of when it applies. The API might return billing at 0.95, technical at 0.02, shipping at 0.01 and other at 0.02, with confidence of 0.93. Your code routes the ticket to billing and moves on.
Two details are worth stealing for your own implementations. First, always include a fallback option such as "other": when none of your categories fit, the fallback gives the model somewhere honest to put the case, and gives you a review queue instead of a forced wrong answer. Second, the per-option probabilities are diagnostic gold. If billing and refunds keep splitting 0.51/0.49 on the same kind of ticket, your category definitions — not the model — are probably the problem.
3. Score: "Grade this against a rubric"
A score question grades an input against an ordered rubric of 2 to 10 levels and returns a probability-weighted average of the level indices — which means the score can land between two levels, carrying the model's uncertainty inside the number itself.
OpenAI's worked example is bug severity, with three levels: Cosmetic (index 0), Workaround available (index 1) and Fully blocked (index 2). For the report "Export fails in Safari but works in Chrome," suppose the API assigns probabilities of 0.1, 0.7 and 0.2 to those three levels. The score is the weighted average:
0 × 0.1 + 1 × 0.7 + 2 × 0.2 = 0 + 0.7 + 0.4 = 1.1
A score of 1.1 says "mostly a workaround-available bug, leaning slightly toward worse" — more information than any single label could carry, in a form a triage system can sort, threshold and trend over time. Like choice answers, score answers also include the full per-level probabilities and a confidence figure, so your code can escalate the cases where the distribution is flat and the model is genuinely torn.
| Type | You supply | You get back | Typical job |
|---|---|---|---|
| Predicate | A condition to check | Probability 0–1 that it holds | Damage checks, moderation flags, relevance filters |
| Choice | A fixed list of options | The picked value, probabilities for all options, confidence | Ticket routing, categorisation, next-action selection |
| Score | An ordered rubric of 2–10 levels | Probability-weighted score (can fall between levels), probabilities, confidence | Severity grading, quality scoring, prioritisation |
How a Decisions request actually works
A request to POST /v1/decisions has three parts, per the official API reference:
model— currently alwaysgpt-6-luna; it is the only model the endpoint supports.input— the shared evidence every question is judged against: a text string, messages that can include images, or structured JSON passed natively.questions— the list of questions, each with a type, a name, instructions, and its allowed choices or score levels.
The response is an answers array, in question order, echoing each question's name so your code can match answers to questions without guesswork.
The headline capacity number is 400 questions in a single request, raised from the beta limit. That changes the economics of batch work: one product photo can be checked for damage, classified by category and scored for listing quality in a single call, against the same shared input. One support conversation can be routed, sentiment-checked and urgency-scored in one round trip. Independent questions belong in the same request; if a later decision genuinely depends on an earlier answer, OpenAI's guidance is to send a second request rather than fake the dependency.
Inputs are flexible. Text is the obvious case. Images can be sent inline as base64 or as publicly accessible URLs, and GA added the ability to put images inside individual question instructions, so each question can compare its own candidate image against a shared reference. JSON input is native — you can hand the endpoint a structured record, such as a ticket plus its order data, without flattening it into prose first.
Two GA additions deserve attention. Prompt caching lets repeated shared context — a long policy document, a product catalogue, a reference image — be reused across requests at the discounted cached rate. And native GPT-Live integration means voice applications can fire decisions mid-conversation as transcripts arrive, so a voice agent can decide to clarify, escalate or act while the caller is still speaking. OpenAI also offers a Decisions Playground on its platform, so you can test questions against your own text and images before writing code — worth an hour before any integration work.
Speed: from seconds to ~100 milliseconds
Latency is the real product here, and OpenAI's numbers are specific. The company says the Decisions API runs up to 10x faster than running the same gpt-6-luna model through the Responses API. Handa's framing is the memorable one: response times shrank from 1–3 seconds to 100–180 milliseconds.
Treat those as vendor figures — OpenAI has not published a methodology you can audit, and your latency will vary with input size, image payloads and region. But even if you discount the claim heavily, the direction is structural, not marketing. A general chat call generates an answer token by token; a decision call evaluates predefined options and returns a compact verdict. There is simply less work per request, and the 400-question batching means the per-decision overhead drops further at volume.
Why does ~100ms matter? Because it moves AI judgment inside interactive loops that a 2-second call could never sit in. A voice agent cannot pause for two seconds to decide whether to escalate — the conversation dies. A checkout flow cannot wait two seconds to categorise a transaction or check a document. An agent framework choosing its next tool cannot spend seconds on every fork. At 100–180ms, the decision layer stops being a step the user notices and becomes plumbing. That is also the context for Luna's other big move this week — entering private preview in Google Cloud's Model Garden, which we covered in our OpenAI models on Google Cloud guide: OpenAI is pushing its fast tier everywhere decisions get made.
Pricing: the arithmetic, done honestly
The rate card is simple, and it is worth being precise about it, because "cheap" claims in AI usually dissolve under arithmetic. Per OpenAI's pricing page and the GA guide:
| Item | Price |
|---|---|
| Input tokens (uncached) | $0.10 per 1M tokens |
| Cached input tokens | $0.01 per 1M tokens |
| Output tokens | $0 — not charged |
| Cache writes | Billed at Luna's standard prompt-caching rates ($0.125 per 1M for 30-minute retention, $0.25 per 1M for 12-hour retention) |
So the centre of the pricing model is: you pay for input, and only input. Cache hits are discounted by 90%; cache writes are billed, so caching pays when shared context is genuinely reused — exactly the workload shape Decisions is built for. Regional processing premiums and long-context multipliers can still apply, as they do across the API.
Now the worked example. Say you route support tickets, and each routing decision takes 500 input tokens of context — the ticket text plus a compact instruction block. You make 10 million routing decisions a month.
- Total input: 10,000,000 decisions × 500 tokens = 5,000 million tokens (5B)
- Cost on Decisions: 5,000 × $0.10 = $500
- Per decision: $500 ÷ 10,000,000 = $0.00005 — five hundred-thousandths of a dollar
- If that shared context were fully cached instead: 5,000 × $0.01 = $50
Scale it down and it stays sane: one million decisions at the same size cost $50, which is exactly the per-million figure in OpenAI's own comparison example (more on that below).
Compare that with doing the same job through full chat completions. The input bill is the same $0.10 per million — Luna's regular API price is $0.10 per 1M input and $0.50 per 1M output — but a chat model also writes an answer, and you pay for every token of it. Even a terse 25-token JSON reply per decision adds 10,000,000 × 25 = 250M output tokens, or $125 on top of the same $500, before you count the parsing, validation and retry logic your team has to maintain — and the reply arrives in seconds, not ~100ms. The output charge is not the biggest cost of the old approach; the latency and the plumbing are. Decisions removes all three at once.
For calibration against the rest of the market, that speed-at-price point is part of a wider pattern we have tracked in fast-inference systems such as Mercury 3's diffusion approach: the industry is splitting into models that write, and models that react.
Decisions vs Responses API vs Structured Outputs
OpenAI now offers three ways to get machine-usable answers out of its models, and picking the wrong one is the easiest mistake in this launch. OpenAI's own guidance draws the lines clearly:
| Decisions API | Responses API (general) | Structured Outputs (on Responses) | |
|---|---|---|---|
| What it returns | A probability, a choice, or a score | Generated text, tool calls, full model responses | A generated object that follows your JSON schema |
| Output tokens billed | No | Yes | Yes |
| Speed | ~100–180ms per OpenAI; up to 10x faster than Responses | Standard generation latency (Handa cites 1–3s for equivalent decision calls) | Standard generation latency |
| Model choice | gpt-6-luna only | Full model range, including flagship Astra | Full model range |
| Best for | Classification, routing, scoring, filtering at volume | Conversation, generation, reasoning, tool use | Extraction, form filling, any answer shaped like your own object |
| Explanations | None — numbers only | Yes, in prose | Only if your schema includes a field for one |
The rule of thumb: if your code needs a verdict, use Decisions. If your code needs an artefact — extracted fields, a drafted reply, a written rationale — use the Responses API, with Structured Outputs when the artefact's shape matters. Plenty of real systems need both: Decisions to route and prioritise, a full model to do the work once the routing is right. Anthropic's recent multi-agent releases, covered in our Claude Duet guide, point at the same architecture from the other direction — small, fast judgment calls steering larger, slower work.
Decisions vs Jev: the honest comparison
None of this exists in a vacuum. TypeSafe's Jev created this category — the "decision model" or super-classifier that takes a set of options and returns a pick with probabilities and confidence — and the market rewarded it with a valuation of around $7.6 billion. OpenAI's GA announcement, covered by Unite.ai and WebProNews among others, is a direct challenge. TradingView's report likewise framed the launch around the Jev rivalry and the named launch customers: Box, Datadog, Ramp, Sierra and Speak.
Here is the part of the comparison OpenAI deserves credit for publishing against itself. In the comparison example in OpenAI's own documentation — 1 million classifications of 500 tokens each — the numbers are:
- Input volume: 1,000,000 × 500 = 500M tokens
- Jev: $21 (at Jev's published $0.042 per 1M input tokens: 500 × $0.042 = $21)
- Decisions API: $50 (500 × $0.10 = $50)
On pure, uncached, text-classification volume, Jev is cheaper — less than half the price. If your workload is exactly that shape and price is the deciding factor, Jev wins the round, and any review that hides this is not being straight with you. TypeSafe's own Jev documentation is worth reading if you are evaluating the category seriously.
Decisions' counter-argument is everything around the raw rate. It lives inside the OpenAI platform your team may already use, with the same keys, billing, compliance posture and support contracts. It is multimodal — images are first-class inputs, judged against the same questions as text. It integrates natively with GPT-Live for voice. Its cached-input rate of $0.01 per million undercuts Jev's flat rate for high-reuse workloads, where the same context is evaluated repeatedly. And its compliance story — Zero Data Retention and HIPAA eligibility for qualifying customers, regional processing in the US and Europe — arrives with OpenAI's enterprise paperwork already attached.
The honest summary: Jev is the purpose-built specialist and, on headline price, still the cheaper classifier. Decisions is the ecosystem play — slightly pricier per uncached token, broader in inputs, and dramatically easier to adopt if your stack already runs on OpenAI.
Who should use it: four workloads that fit today
Support triage and routing. The choice question was practically designed for this: route by department, score by urgency, predicate-check for escalation triggers, all in one request per ticket. If you are evaluating tools in this space, our best AI meeting assistants roundup covers the adjacent workflow of capturing and acting on conversations — Decisions is the kind of layer those tools increasingly sit on top of.
Content moderation. Predicate questions map directly onto policy checks — does this post, image or listing violate rule X — with a probability you can threshold: auto-remove the clear violations, queue the borderline band for humans, pass the rest. Classification is also quietly becoming the workhorse inside AI security tooling; for the offensive side of that same shift, see our ARTEX AI hacking tool guide.
Transaction categorisation. Finance teams classifying transaction descriptions into categories are a natural fit — it is telling that Ramp is a named launch customer. Choice questions handle the category; score questions can grade confidence-adjacent dimensions such as how likely a transaction is to need review.
Agent routing and voice. Agents constantly face small forks: which tool, which sub-agent, retry or escalate, clarify or proceed. Those forks are decisions, and at 1–3 seconds each they dominate an agent's runtime. At ~100ms, with GPT-Live integration for voice, the decision layer stops being the bottleneck.
Limitations you should plan around
- One model only. The endpoint supports
gpt-6-lunaand nothing else. There is no way to trade up to a smarter model inside the same call for hard cases — you build the escalation path yourself, typically by thresholding confidence and falling back to a bigger model on the Responses API. - No published accuracy benchmarks. OpenAI has not released accuracy or calibration benchmarks for the endpoint. The probabilities are the model's estimates; whether 0.9 means "right nine times out of ten" on your data is an empirical question only your labelled examples can answer.
- Thresholds are your homework. OpenAI's guidance is to set decision thresholds from your own labelled examples, weighing false-positive against false-negative costs. Budget the evaluation work; it is the difference between a demo and a production system.
- Numbers, not reasons. Decisions returns no explanations. Where an audit trail or a human-readable rationale is required, pair it with a generative call or look elsewhere.
- Dependent decisions need separate requests. Questions in one request are evaluated independently against shared input. Chained logic means multiple calls, which eats into the latency advantage if you overdo it.
FAQ
What is the OpenAI Decisions API? A dedicated OpenAI endpoint (POST /v1/decisions) that returns typed judgments instead of generated text: a probability that a condition holds, a choice from options you supply, or a score against a rubric you define. It became generally available on October 22, 2026, runs only on gpt-6-luna, and is built for classification, routing and scoring inside applications. OpenAI's GA announcement on its developer community has the launch summary.
How much does the Decisions API cost? $0.10 per million input tokens, $0.01 per million cached input tokens, and no charge for output tokens. Cache writes are billed at Luna's standard prompt-caching rates. At 500 input tokens per decision, that works out to $50 per million decisions before caching — check the worked examples above for the full arithmetic.
How fast is it, really? OpenAI claims up to 10x faster than the Responses API, and its API product lead Nikunj Handa cites response times falling from 1–3 seconds to 100–180 milliseconds. Those are OpenAI's figures, not independent benchmarks, so measure on your own traffic — but the structural reason for the speed (no text generation) is sound.
Decisions API or Structured Outputs — which do I need? If you need a probability, a pick from a fixed list, or a rubric score, use Decisions. If you need the model to produce an object in your own JSON schema — extracted fields, a drafted answer, a written explanation — OpenAI directs you to Structured Outputs on the Responses API.
How does it compare with TypeSafe's Jev? Jev created the decision-model category and is cheaper on pure classification volume: OpenAI's own docs example prices 1M classifications of 500 tokens at $21 on Jev versus $50 on Decisions. Decisions counters with multimodal inputs, GPT-Live voice integration, a $0.01 cached rate for high-reuse workloads, and OpenAI's platform and compliance ecosystem.
Is the Decisions API suitable for regulated workloads? OpenAI offers Zero Data Retention and HIPAA eligibility for qualifying customers, plus regional processing in the US and Europe. "Eligible" is doing work in that sentence — confirm your organisation's status and agreements with OpenAI before routing regulated data through any endpoint.
Verdict
The Decisions API is OpenAI admitting that a huge share of production AI was never really about generation — it was about judgment, delivered fast, cheaply and in a shape code can use. The GA package is strong: ~100ms-class responses by OpenAI's account, input-only pricing that survives honest arithmetic, 400 questions per request, multimodal inputs, voice integration and an enterprise compliance story. Jev remains the cheaper pure classifier and the category's originator, and OpenAI has not published the accuracy data that would settle the quality argument. But for the large number of teams already building on OpenAI, a decision layer that drops into the existing stack — no new vendor, no new contract — will be very hard to resist. If your agents, queues or pipelines are spending seconds and output tokens on questions with five possible answers, this is the first call you should re-platform.
Reader reviews
Loading reviews…